
Key Takeaways
- All four major AI engines share a similar training recipe (pretraining, instruction tuning, and preference optimization), but each one is tuned toward a different outcome.
- Public preference-training datasets show a documented shift from a single accept-or-reject judgment to a five-axis grading rubric, and that newer rubric appears to reward more structured, list-shaped answers.
- Perplexity leans on live retrieval and citations. Claude’s edge is depth and long-form reasoning, while ChatGPT covers the broadest set of use cases and Gemini’s advantage comes from native access to Google’s own ecosystem.
- Third-party benchmark testing changes every few months, so treat any single comparison as a snapshot, not a permanent ranking.
- Measuring AI visibility means watching citation frequency, brand mentions, and source diversity, not just keyword rank.
You already know what GEO is. You’ve read the definitions, sat through the LLMO comparisons, and seen the “AI search is changing everything” takes. What’s still missing from most of that content is GEO by platform: the actual, mechanical differences in how ChatGPT, Claude, Gemini, and Perplexity decide what to surface. Clients are asking this question directly, and most of the guidance out there treats “optimize for AI search” as one strategy instead of four.
Here’s the ground rule before we go further: nobody outside OpenAI, Anthropic, Google, and Perplexity knows the current, exact formula any of these engines uses to rank or select content. Those systems are proprietary, and they shift on a rolling basis. What we can do is walk through the documented mechanisms these systems share, where they genuinely diverge in practice, and what that means for your tactics and measurement, platform by platform.
Why AI Engines Aren’t the Same
Every major AI engine on the market runs a version of the same recipe: pretraining on a massive amount of text, instruction tuning to make the model follow directions, preference optimization to shape its behavior, and product-level decisions about what to retrieve and rank when someone asks it something. That shared foundation is exactly why a lot of GEO optimization by platform advice sounds interchangeable. It’s also why that advice tends to underperform once you actually test it against a specific engine.
Each engine bends that shared recipe toward a different job. Perplexity built its product around source-based retrieval, so its answers read closer to a research assistant than a chatbot: citation-heavy, and grounded in whatever’s currently live on the web. Claude was tuned to go deep, reasoning through multi-step problems, holding context across long documents, and working well inside agent-style workflows where accuracy compounds over many steps. ChatGPT covers the widest surface area of the group, with the largest install base and voice, vision, and multimodal features layered on top of a general-purpose core. Gemini’s biggest edge shows up the moment a task touches anything inside Google’s own ecosystem, whether that’s Docs, Sheets, YouTube, or Workspace data the other three simply can’t see.
None of that comes down to taste. A single, generic “GEO best practices” checklist misses this entirely, because the differences between these systems come from how each one was built and what it’s optimized to reward, not from surface-level style choices.
How GenAI Actually Decides What to Say
Decision-making inside these systems happens in three layers, and understanding them explains most of what looks like unpredictable behavior from the outside.
Training-time shapingcomes first. A model reads an enormous amount of text during pretraining, then goes through instruction tuning to learn to follow directions, then preference optimization, commonly RLHF or RLAIF, to learn which of two possible answers a human grader preferred. This is the stage where a model’s default habits get set: how much it hedges, how much detail it volunteers, how polite it sounds by default.
Inference-time selectionhappens next, every time you send a prompt. The model scores and weights candidate responses, usually through a reward model or alignment layer trained on those same human preference judgments from the step above.
Product-time retrievalis the layer that varies most visibly by platform. Some engines pull in outside retrieval-augmented generation, while others rely more on patterns already baked into the model’s weights through fine-tuning. This layer explains a lot of why some products feel more like a search engine and others feel more like a conversation
Two public datasets make the preference-tuning layer concrete instead of theoretical. Anthropic published hh-rlhf in 2022: 169,000 rows, each one a binary call on which of two responses a human grader preferred. Nvidia’s HelpSteer2, published in 2024, grades responses across five separate axes instead of one: helpfulness, correctness, coherence, complexity, and verbosity.
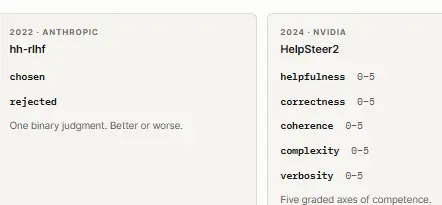
An independent analysis of both files found that under HelpSteer2’s five-axis rubric, more list-shaped, enumerated answers scored higher in a majority of the pairs examined. That’s a plausible partial explanation for why AI-generated answers so often default to bullets and numbered steps, but it’s worth treating as an informed inference rather than a settled fact. The researcher who ran the analysis was careful to frame it the same way.
One caveat matters more than the data itself: neither file reflects how Anthropic or Nvidia trains models today. They’re historical snapshots from a specific year at a specific lab, not a live map of any current engine’s ranking logic. Treat them as a useful, citable window into how preference tuning has worked in at least these documented cases, not a spec sheet for what’s happening right now.
What Changes by Engine
Perplexity: Built For
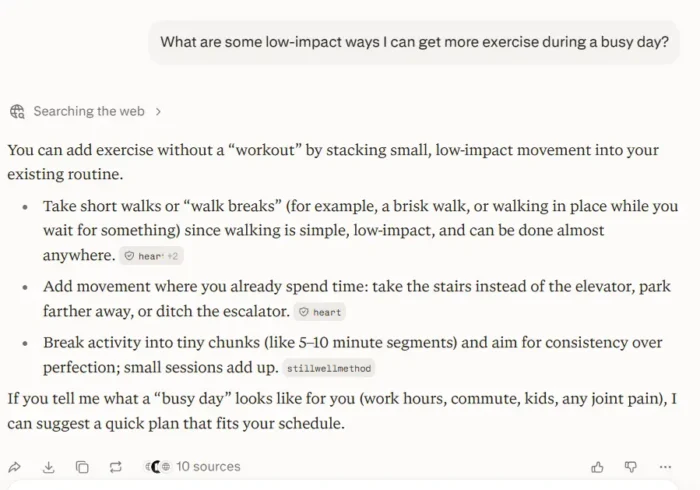
Perplexity’s whole product is oriented around citations and fresh retrieval, and that shows up in the output. Independent testing that runs ChatGPT vs. Claude vs. Gemini vs. Perplexity through identical prompt batches consistently ranks Perplexity ahead on citation accuracy and real-time grounding, which tracks given it’s pulling from the live web at query time instead of relying mostly on training data. Where it falls short is anything creative or long-form. Ask it to draft a full article, and the output tends to read functional rather than polished.
Claude: Built For Depth
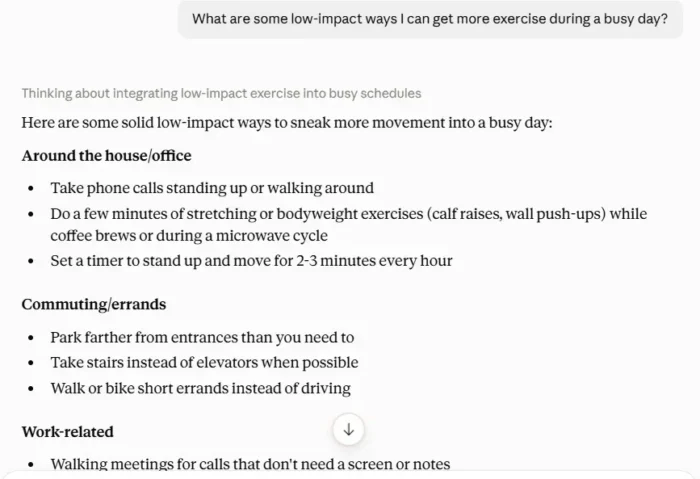
Claude tends to show up strongest on tasks that require holding a lot of context and reasoning through it carefully. Testing rounds that track calibration, meaning how often a model’s confidence matches whether it’s actually right, have repeatedly put Claude ahead of the field, particularly on claims where being wrong actually matters. That combination of depth and caution is a big reason teams lean on Claude for long-form content and multi-step agent workflows rather than quick answers.
ChatGPT: Built For Breadth
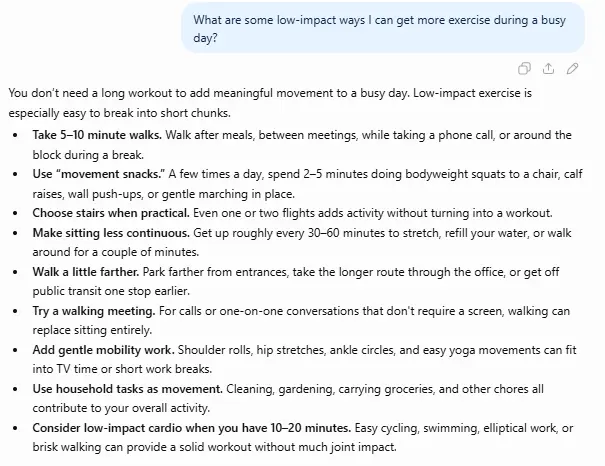
ChatGPT still carries the largest install base of the group and the widest feature set, voice, vision, image generation, browsing, and a long list of plugins layered onto a general-purpose core. That breadth is a real advantage. Several independent testers also note the output quality swings more than the other three without detailed prompting. It’s the most flexible tool here, and flexibility cuts both ways.
Gemini: Built For The Google Ecosystem
Gemini’s advantage rarely shows up in raw model quality alone. It shows up the moment a task touches Gmail, Docs, Sheets, or YouTube, where Gemini can actually read and act on your own data instead of talking about it in the abstract. For teams already living inside Google Workspace, that access matters more day to day than a benchmark score.
Keep the bigger takeaway simple: none of these four wins across the board, and most credible testing in this space lands on some version of using more than one tool, matched to the task, rather than crowning a single winner. Revisit that assumption every few months. Standings shift, and last quarter’s leaderboard isn’t this quarter’s.
What Tactics Change by Engine
Here’s where this gets practical. Once you understand the mechanism and positioning differences above, the tactical shifts stop feeling arbitrary. They follow directly from what each engine actually rewards.
Because Perplexity leans this hard on retrieval, prioritize factual,ch, cited statistics, and clearly attributable claims perform better here than persuasive copy. Structure your content so a system pulling live answers can lift a clean, self-contained statement out of it without needing the surrounding context
Claude rewards depth over surface-level breadth, so long-form content with strong headings, a clear argument, and an experiential point of view earns more traction here than a shallow listicle covering the same ground. If you have real experience running the strategy you’re writing about, say so directly. That’s the kind of signal this engine’s reasoning tends to weight.[Internal link suggestion: long-form content / E-E-A-T guide]
ChatGPT serves answers across the widest range of surfaces, so content that works as both a full explainer and a set of shorter, atomized pieces tends to travel further here. Conversational framing helps too, since a large share of ChatGPT’s traffic comes through follow-up questions rather than one query.
Gemini’s advantage comes from the Google ecosystem, so optimize for visibility inside it specifically: clean entity definitions, structured data, and schema markup that helps Google’s own systems understand what your content is actually about. This is less about persuasive writing and more about making your content legible to a system that already has your brand’s data sitting in other Google products.
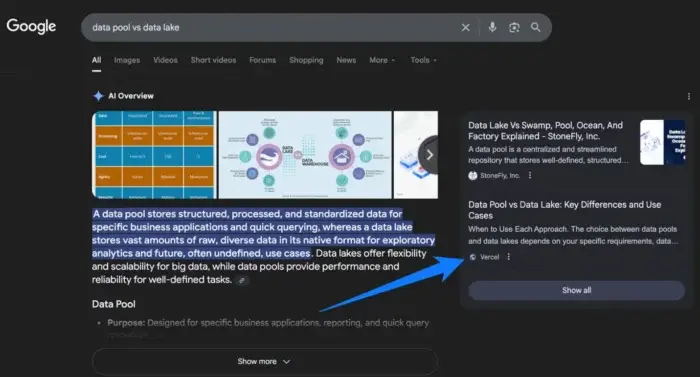
One more distinction is worth real space here, because it’s one of the most practical takeaways in this piece: these engines don’t weight sources the same way. Some lean more heavily on a brand’s own site content. Others lean more on third-party mentions and citations from outlets a brand doesn’t control. Several reward structured, schema-marked data over plain prose, regardless of who published it. Knowing which lever matters most for a given engine changes where you spend your time: publishing more on your own domain, earning more third-party citations, or investing in structured data that makes your existing content easier to parse.
KPIs for Tracking Performance Across Engines
Traditional rank tracking doesn’t map cleanly onto AI answers, so you need a different measurement set once you’re optimizing for GEO by platform instead of just SEO.
Start with citation frequency: how often your content actually gets cited as ans separately, since showing up by name in an AI answer still carries value even without a citation attached. Watch whether your content lands inside the direct answer summary or gets pushed to a secondary link a user has to click through to find, because that placement difference matters more here than it ever did in traditional search
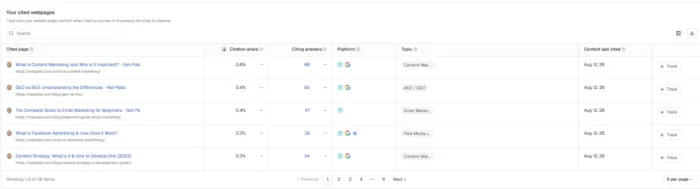
Content freshness rounds this out, especially for retrieval-heavy engines like Perplexity, where how recently you updated a page can affect whether it gets pulled into an answer at all. None of these metrics replace the KPIs you already track. They sit alongside them, and together they give you a fuller picture of whether your content is showing up where your buyers are actually asking questions.
Do ChatGPT, Claude, Gemini, and Perplexity Use the Same Ranking Algorithm?
No. All four share a similar training foundation, pretraining, instruction tuning, and preference optimization, but each product layers different retrieval and ranking choices on top of it. That’s why the same query can produce different answers across platforms.
What Is RLHF, And Why Does It Matter For GEO?
RLHF stands for reinforcement learning from human feedback: human graders rank possible responses, and the model gets tuned to favor the ones graders preferred. It matters for GEO because it shapes what a model considers a “good” answer, including, in at least some documented cases, a preference for more structured, list-style content.
Is GEO Different for Every AI Platform?
Yes, meaningfully so. Each engine optimizes for a different outcome and pulls from differentatform-specific approach
Conclusion
The mechanics genuinely differ by engine, and that’s not changing as these products keep evolving. But the goal was never to master four black boxes. It’s to understand the shared foundations well enough to make an informed, platform-specific bet, then revisit that bet as the landscape shifts, because it will.
That’s the kind of work we do at NP Digital: tracking how these engines behave in practice, testing content against real prompts, and adjusting strategy as each platform updates. Start with one platform where your buyers already spend time, apply what’s above, and measure it. Then expand from there.
