
Building Multi-Tier AI Agent Memory with TypeScript and SQLite-vec
SitePoint TeamPublished inAI·Programming·Databases·
September 25, 2026
The AI briefing for Developers
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
SitePoint Premium
Stay Relevant and Grow Your Career in Tech
- Premium Results
- Publish articles on SitePoint
- Daily curated jobs
- Learning Paths
- Discounts to dev tools
7 Day Free Trial. Cancel Anytime.
AI agents built on top of LLMs suffer from a fundamental constraint: they forget everything the moment a conversation ends. For developers building TypeScript AI agent memory systems, the typical answer involves reaching for a cloud-hosted vector database. But for single-agent deployments, edge scenarios, and local-first architectures, that dependency is unnecessary overhead. A SQLite-vec Node.js tutorial that covers real multi-tier memory, not just vector search, fills a gap that most guides ignore entirely. This article builds a complete, modular memory store in TypeScript backed by SQLite and sqlite-vec, unifying episodic, semantic, and procedural memory tiers in a single local database with zero external service dependencies beyond Node.js itself.
How to Build Multi-Tier AI Agent Memory with TypeScript and SQLite-vec
- Initialize a TypeScript project with better-sqlite3 and sqlite-vec dependencies, configuring strict mode and CommonJS modules.
- Load the sqlite-vec runtime extension into your better-sqlite3 database instance and enable WAL mode.
- Define a multi-tier schema with episodic (append-only log), semantic (metadata + vec0 virtual table), and procedural (structured rules) tables.
- Implement episodic memory methods to log interaction turns and retrieve recent non-compacted episodes by session.
- Store semantic memories by transactionally inserting content metadata and Float32Array embeddings into the vec0 virtual table with cosine distance.
- Query semantic memory using sqlite-vec’s MATCH operator for k-nearest-neighbor retrieval, tracking access counts for LRU eviction.
- Extract procedural rules as structured condition/action pairs with confidence scores and episode provenance.
- Wire all three tiers into an agent loop that recalls context, applies rules, generates responses, and triggers episodic compaction.
Table of Contents
Why AI Agents Need Multi-Tier Memory
The Stateless Agent Problem
Every raw LLM call is stateless. The model receives a prompt, produces a response, and discards all internal state. When you build an agent atop stateless calls without a persistence layer, the consequences compound quickly: the agent repeats mistakes a user already corrected and asks for information the user provided three turns ago, yet it cannot adapt its behavior based on accumulated experience. This is not a minor UX annoyance. It fundamentally limits an agent’s usefulness in any scenario requiring continuity, whether that is multi-session task management, personalized assistance, or iterative problem-solving. The agent appears intelligent in isolation but incoherent over time.
Episodic, Semantic, and Procedural: A Cognitive Architecture
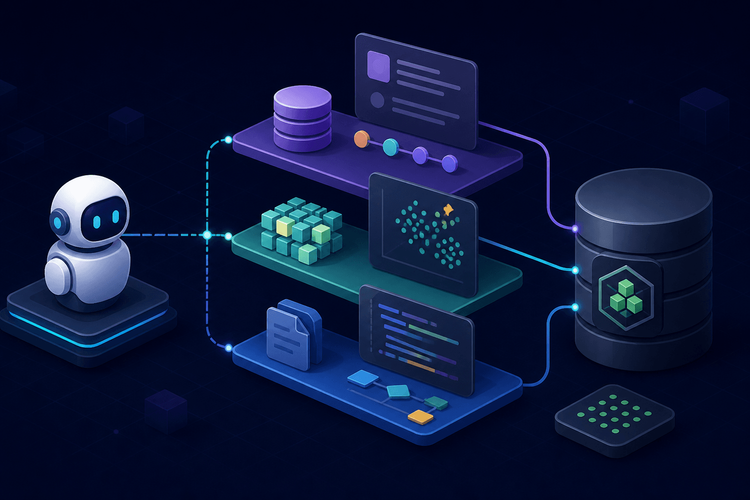
A three-tier AI agent memory architecture draws from cognitive science by separating memory into distinct layers:
- Episodic memory records what happened: timestamped interaction logs, the raw record of every exchange between the agent and its environment, partitioned by session.
- Semantic memory distills what the agent knows. These are facts, knowledge fragments, and their vector embeddings, optimized for retrieval by similarity rather than recency.
- Rather than storing free text, procedural memory extracts actionable rules, user preferences, and behavioral patterns that guide future decisions.
Most vector store tutorials stop at semantic memory. But an agent that can search its knowledge base yet cannot recall what happened last session (episodic) or what rules it learned (procedural) is still fundamentally incomplete. All three tiers are necessary for an agent that genuinely learns.
An agent that can search its knowledge base yet cannot recall what happened last session (episodic) or what rules it learned (procedural) is still fundamentally incomplete.
Why SQLite and sqlite-vec for Local Agent Memory
Cloud vector databases like Pinecone, Weaments. For a single-agent or edge deployment, they introduce network latency and cost, plus operational complexity and an external runtime dependency. SQLite eliminates all of these
sqlite-vec is a SQLite extension that adds vector similarity search capabilities directly to SQLite. It provides virtual tables (using the vec0 module) that store float32 vectors and support k-nearest-neighbor queries with distance functions like cosine and L2. Cosine distance is not the default; vec0 uses L2 (Euclidean) distance unless the column declaration explicitly specifies distance_metric=cosine. sqlite-vec loads as a runtime extension, requires no separate server process, and works with existing SQLite tooling.
better-sqlite3 is the preferred SQLite binding for Node.js in synchronous agent loops. It provides a synchronous API (no callback or promise overhead in tight loops), supports extension loading, and requires zero configuration beyond installation
Project Setup and Dependencies
Initializing the TypeScript Project
The project requires Node.js 18.13+ (required for the node:test runner’s describe/it exports used later) and uses TypeScript in strict mode. The module system choice here is CommonJS for maximum compatibility with better-sqlite3’s native bindings, though ESM is possible with additional configuration.
mkdir agent-memory &&cd agent-memorynpm init -ynpminstall better-sqlite3@11 sqlite-vec@0.1npminstall-D typescript @types/better-sqlite3 @types/nodenpx tsc --initNote: Pin dependency versions as shown above (replace with current stable versions at time of use). The sqlite-vec extension API and better-sqlite3’s loadExtension behavior may change across major versions.
The generated tsconfig.json should be tightened for this project:
{"compilerOptions":{"target":"ES2022","module":"commonjs","strict":true,"esModuleInterop":true,"outDir":"./dist","rootDir":"./src","declaration":true,"sourceMap":true,"resolveJsonModule":true},"include":["src/**/*"]}Add the following scripts to package.json:
{"scripts":{"build":"tsc","start":"node dist/agent-loop.js"}}To compile the project, run npx tsc. To execute any compiled file, run node dist/<filename>.js. For example, after creating src/db.ts below, compile with npx tsc and verify with node dist/db.js. For development without a manual compilation step, use npx tsx src/<filename>.ts (install tsx as a dev dependency if desired).
Loading sqlite-vec as a Runtime Extension
sqlite-vec distributes prebuilt binaries for major platforms (x64 Linux, x64/ARM64 macOS, x64 Windows) through its npm package. The sqlite-vec npm module exports a load() function that accepts a better-sqlite3 database instance and loads the compiled extension for the current platform. On platforms without prebuilt binaries, compilation fromment headers
import Database from"better-sqlite3";import*as sqliteVec from"sqlite-vec";exportfunctioncreateDatabase(dbPath:string): Database.Database {const db =newDatabase(dbPath);db.pragma("journal_mode = WAL");sqliteVec.load(db);const version = db.prepare("SELECT vec_version()").pluck().get()asstring;console.log(`sqlite-vec version:${version}`);return db;}The sqliteVec.load(db) call resolves the extension path for the current platform internally. The vec_version() scalar function confirms the extension is active and returns its version string, serving as a quick sanity check during initialization.
Designing the Multi-Tier Schema
Episodic Memory Table
The episodic table functions as an append-only log. Each row represents a single turn in a conversation, tagged with a session identifier for partitioning and a timestamp for ordering. A token_count column supports token-aware retrieval later, enabling the agent to budget its context window.
Design rationale: this table is never updated in place. Rows are inserted and eventually either compacted into semantic memory or archived. Indexes on session_id and timestamp support the two primary access patterns: retrieving recent turns within a session and selecting old episodes for compaction.
Semantic Memory Table with Vector Column
sqlite-vec uses virtual tables with the vec0 module to store and index vectors. The semantic memory tier pairs a regular table holding metadata (content text, source episode linkage, access tracking) with a vec0 virtual table holding the embedding vectors. The embedding dimension must match your model’s output dimension: 384 dimensions for all-MiniLM-L6-v2 (as specified in the model card), 1536 for OpenAI’s text-embedding-3-small (default output dimension; this model supports variable output dimensions), and so on. You fix the embedding dimension at table creation time and must recreate the table to change it.
Procedural Memory Table
Procedural memory stores structured rules with a confidence score between 0 and 1. Each rule links back to the last_applied timestamp enables LRU-style eviction of stale rules
Why structured condition/action fields instead of free text? They can be parsed and applied programmatically rather than relying on the LLM to interpret them correctly each time, which makes agent behavior more predictable.
import Database from"better-sqlite3";exportfunctioninitializeSchema(db: Database.Database,embeddingDimension:number=384):void{if(!Number.isInteger(embeddingDimension)||embeddingDimension <1||embeddingDimension >65536){thrownewRangeError(`Invalid embeddingDimension:${embeddingDimension}. Must be a positive integer ≤ 65536.`);}const dim = embeddingDimension;const initAll = db.transaction(()=>{db.exec(`-- Episodic memory: append-only interaction logCREATE TABLE IF NOT EXISTS episodic_memory (id INTEGER PRIMARY KEY AUTOINCREMENT,session_id TEXT NOT NULL,role TEXT NOT NULL CHECK(role IN ('user', 'assistant', 'system')),content TEXT NOT NULL,timestamp TEXT NOT NULL DEFAULT (datetime('now')),token_count INTEGER NOT NULL DEFAULT 0,compacted INTEGER NOT NULL DEFAULT 0);`);db.exec(`CREATE INDEX IF NOT EXISTS idx_episodic_sessionON episodic_memory(session_id, timestamp);`);db.exec(`CREATE INDEX IF NOT EXISTS idx_episodic_timestampON episodic_memory(timestamp);`);db.exec(`-- Semantic memory: metadata tableCREATE TABLE IF NOT EXISTS semantic_memory (id INTEGER PRIMARY KEY AUTOINCREMENT,content TEXT NOT NULL,source_episode_id INTEGER,created_at TEXT NOT NULL DEFAULT (datetime('now')),access_count INTEGER NOT NULL DEFAULT 0,FOREIGN KEY (source_episode_id) REFERENCES episodic_memory(id));`);db.exec(`-- Semantic memory: vector store (sqlite-vec virtual table)-- cosine distance is explicit via column declaration; L2 is the vec0 defaultCREATE VIRTUAL TABLE IF NOT EXISTS semantic_memory_vec USING vec0(id INTEGER PRIMARY KEY,embedding float[${dim}] distance_metric=cosine);`);db.exec(`-- Procedural memory: extracted rules and preferencesCREATE TABLE IF NOT EXISTS procedural_memory (id INTEGER PRIMARY KEY AUTOINCREMENT,rule_condition TEXT NOT NULL,rule_action TEXT NOT NULL,confidence REAL NOT NULL DEFAULT 0.5 CHECK(confidence >= 0 AND confidence <= 1),source_episode_ids TEXT NOT NULL DEFAULT '[]',created_at TEXT NOT NULL DEFAULT (datetime('now')),last_applied TEXT);`);db.exec(`CREATE INDEX IF NOT EXISTS idx_procedural_confidenceON procedural_memory(confidence);`);});initAll();}Note the vec0 virtual table declaration: the embedding dimension is validated as a safe positive integer before interpolation into DDL, and distance_metric=cosine is specified explicitly (the vec0 default is L2/Euclidean). The semantic_memory_vec table’s id column must be manually kept in sync with semantic_memory.id since virtual tables do not support foreign keys. The storeSemantic() method below wraps both inserts in a transaction to prevent orphaned rows. All DDL is wrapped in a transaction so that if any statement fails (e.g., CREATE VIRTUAL TABLE fails because sqlite-vec is not loaded), none of the tables are committed, preventing a partial schema.
Building the Memory Store Module
This section constructs the complete agent-memory-store.ts module incrementally. Each method addresses a specific tier of the memory architecture.
The AgentMemoryStore Class Interface
The public API exposes seven methods spanning all three memory tiers plus a compaction operation. The constructor accepts a database file path, embedding dimension, and a default compaction age in minutes, used as the default value for the maxAgeMinutes parameter of compactEpisodes().
import Database,{ Statement }from"better-sqlite3";import{ createDatabase }from"./db";import{ initializeSchema }from"./schema";exportinterfaceEpisodicRecord{id:number;session_id:string;role:"user"|"assistant"|"system";content:string;timestamp:string;token_count:number;}exportinterfaceSemanticRecord{id:number;content:string;distance:number;access_count:number;}exportinterfaceProceduralRecord{id:number;rule_condition:string;rule_action:string;confidence:number;source_episode_ids:number[];last_applied:string|null;}functionfloat32ToBuffer(arr: Float32Array): Buffer {return Buffer.from(arr.buffer, arr.byteOffset, arr.byteLength);}exportclassAgentMemoryStore{private db: Database.Database;private embeddingDimension:number;private compactionThreshold:number;private stmtLogEpisode: Statement;private stmtGetRecentEpisodes: Statement;private stmtInsertSemanticMeta: Statement;private stmtInsertSemanticVec: Statement;private stmtRecallSemantic: Statement;private stmtUpdateAccessCount: Statement;private stmtStoreRule: Statement;private stmtGetRules: Statement;private stmtSelectCompact: Statement;private stmtMarkCompacted: Statement;constructor(dbPath:string="agent-memory.db",embeddingDimension:number=384,compactionThreshold:number=1440){this.embeddingDimension = embeddingDimension;this.compactionThreshold = compactionThreshold;this.db =createDatabase(dbPath);try{initializeSchema(this.db, embeddingDimension);this.stmtLogEpisode =this.db.prepare(`INSERT INTO episodic_memory (session_id, role, content, token_count)VALUES (?, ?, ?, ?)`);this.stmtGetRecentEpisodes =this.db.prepare(`SELECT id, session_id, role, content, timestamp, token_countFROM episodic_memoryWHERE session_id = ? AND compacted = 0ORDER BY timestamp DESCLIMIT ?`);this.stmtInsertSemanticMeta =this.db.prepare(`INSERT INTO semantic_memory (content, source_episode_id)VALUES (?, ?)`);this.stmtInsertSemanticVec =this.db.prepare(`INSERT INTO semantic_memory_vec (id, embedding)VALUES (?, ?)`);this.stmtRecallSemantic =this.db.prepare(`SELECTv.id,sm.content,v.distance,sm.access_countFROM semantic_memory_vec vINNER JOIN semantic_memory sm ON sm.id = v.idWHERE v.embedding MATCH ?AND k = ?ORDER BY v.distanceLIMIT ?`);this.stmtUpdateAccessCount =this.db.prepare(`UPDATE semantic_memory SET access_count = access_count + 1 WHERE id = ?`);this.stmtStoreRule =this.db.prepare(`INSERT INTO procedural_memory (rule_condition, rule_action, confidence, source_episode_ids)VALUES (?, ?, ?, ?)`);this.stmtGetRules =this.db.prepare(`SELECT id, rule_condition, rule_action, confidence, source_episode_ids, last_appliedFROM procedural_memoryWHERE confidence >= ?ORDER BY confidence DESC`);this.stmtSelectCompact =this.db.prepare(`SELECT id, session_id, role, content, timestamp, token_countFROM episodic_memoryWHERE compacted = 0AND timestamp < datetime('now', '-' || ? || ' minutes')ORDER BY timestamp ASC`);this.stmtMarkCompacted =this.db.prepare(`UPDATE episodic_memory SET compacted = 1 WHERE id = ?`);}catch(err){this.db.close();throw err;}}Writing to Episodic Memory
Each interaction turn is appended as a row. Prepared statements are compiled once in the constructor and reused across calls, which matters in tight agent loops where multiple turns are logged per second.
logEpisode(sessionId:string,role:"user"|"assistant"|"system",content:string,tokenCount:number=0):number{const result =this.stmtLogEpisode.run(sessionId, role, content, tokenCount);returnNumber(result.lastInsertRowid);}getRecentEpisodes(sessionId:string, limit:number=20): EpisodicRecord[]{returnthis.stmtGetRecentEpisodes.all(sessionId, limit)as EpisodicRecord[];}The compacted flag filters out episodes that have already been summarized into semantic memory, preventing the agent from double-counting old context.
Storing and Searching Semantic Memory with sqlite-vec
This is the most technically dense part of the module. Embeddings must be serialized as raw byte buffers (Float32Array converted to Buffer) for insertion into the vec0 virtual table. Retrieval uses sqlite-vec’s k-nearest-neighbor syntax with the MATCH operator and a k parameter to communicate the neighbor count to the vec0 query planner, plus a LIMIT to cap results.
storeSemantic(content:string,embedding: Float32Array,sourceEpisodeId?:number):number{const insertBoth =this.db.transaction((content:string, sourceEpisodeId:number|null, embeddingBuffer: Buffer)=>{const metaResult =this.stmtInsertSemanticMeta.run(content, sourceEpisodeId);const id =Number(metaResult.lastInsertRowid);this.stmtInsertSemanticVec.run(id, embeddingBuffer);return id;});const embeddingBuffer =float32ToBuffer(embedding);returninsertBoth(content, sourceEpisodeId ??null, embeddingBuffer);}recallSemantic(queryEmbedding: Float32Array,topK:number=5): SemanticRecord[]{const queryBuffer =float32ToBuffer(queryEmbedding);const results =this.stmtRecallSemantic.all(queryBuffer,topK,topK)as SemanticRecord[];if(results.length >0){const updateMany =this.db.transaction((ids:number[])=>{for(const id of ids)this.stmtUpdateAccessCount.run(id);});updateMany(results.map((r)=> r.id));}return results;}Key details in this implementation: the MATCH operator on the virtual table column triggers sqlite-vec’s vector search. The k parameter in the WHERE clause communicates the desired neighbor count to the vec0 query planner, and the LIMIT clause caps the final result set. The distance value in results uses the metric specified in the column declaration (cosine, if declared as above). Lower values indicate greater similarity.
The critical constraint is dimension alignment: the embedding model’s output dimension must exactly match the dimension specified when creating the vec0 virtual table.
Extracting and Storing Procedural Rules
Rules use a structured condition/action format rather than free text. Thech rule back to the episodic interactions that produced it, maintaining provenance
storeRule(condition:string,action:string,confidence:number,sourceEpisodeIds:number[]=[]):number{const result =this.stmtStoreRule.run(condition,action,confidence,JSON.stringify(sourceEpisodeIds));returnNumber(result.lastInsertRowid);}getApplicableRules(minConfidence:number=0.7): ProceduralRecord[]{const rows =this.stmtGetRules.all(minConfidence)asany[];return rows.map((row)=>({...row,source_episode_ids:JSON.parse(row.source_episode_ids),}));}Automated Episodic Log Compaction
Unbounded episodic logs degrade both query performance and context window budgets. The compaction strategy selects episodes older than a configurable threshold, marks them as compacted, and returns their content for external summarization. The caller handles the LLM summarization call, keeping this module LLM-agnostic.
compactEpisodes(maxAgeMinutes?:number): EpisodicRecord[]{const ageMinutes =maxAgeMinutes !==undefined? maxAgeMinutes :this.compactionThreshold;if(!Number.isFinite(ageMinutes)|| ageMinutes <0){thrownewRangeError(`maxAgeMinutes must be a non-negative finite number, got:${ageMinutes}`);}const compact =this.db.transaction((age:number)=>{const episodes =this.stmtSelectCompact.all(age)as EpisodicRecord[];for(const episode of episodes){this.stmtMarkCompacted.run(episode.id);}return episodes;});returncompact(ageMinutes);}close():void{this.db.close();}}The transaction wrapper ensures that either all selected episodes are marked as compacted or none are, preventing partial compaction on failure. The caller receives the raw episode content, groups or summarizes it , and stores the result back into semantic memory using storeSemantic()
Wiring Memory into an Agent Loop
A Minimal Agent Loop with Memory Retrieval
The agent loop follows a consistent sequence: receive input, recall relevant semantic context, check procedural rules, generate a response, log the episode, and conditionally trigger compaction. Retrieved memories are injected into the LLM prompt’s system or context section as structured text.
import{ AgentMemoryStore }from"./agent-memory-store";asyncfunctiongenerateResponse(systemContext:string,userMessage:string):Promise<string>{return`Response to:${userMessage}`;}asyncfunctiongetEmbedding(text:string):Promise<Float32Array>{returnnewFloat32Array(384);}exportasyncfunctionagentStep(store: AgentMemoryStore,sessionId:string,userMessage:string):Promise<string>{const userEpisodeId = store.logEpisode(sessionId,"user", userMessage);const queryEmbedding =awaitgetEmbedding(userMessage);const relevantMemories = store.recallSemantic(queryEmbedding,5);const rules = store.getApplicableRules(0.7);const memoryContext = relevantMemories.map((m)=>`[Memory]${m.content}`).join("");const ruleContext = rules.map((r)=>`[Rule] IF${r.rule_condition}THEN${r.rule_action}`).join("");const recentEpisodes = store.getRecentEpisodes(sessionId,10).slice().reverse().map((e)=>`${e.role}:${e.content}`).join("");const systemContext =[memoryContext, ruleContext, recentEpisodes].filter(Boolean).join("");const response =awaitgenerateResponse(systemContext, userMessage);store.logEpisode(sessionId,"assistant", response);return response;}Embedding Generation Strategy
The getEmbedding() function above is deliberately a stub that returns a zero vector. For local-first consistency, the @huggingface/transformers package (the official Hugging Face npm package) provides ONNX-based inference that runs entirely in Node.js without API calls. Models like all-MiniLM-L6-v2 produce 384-dimensional embeddings at roughly 80 MB of ONNX weights, making them practical for CPU inference without a GPU. API-based options from OpenAI or Cohere work but reintroduce a network dependency that conflicts with the local-first design.
The critical constraint is dimension alignment: the embedding model’s output dimension must exactly match the dimension specified when creating the vec0 virtual table. A mismatch produces either insertion errors or corrupted search results.
exporttypeEmbeddingFunction=(text:string)=>Promise<Float32Array>;exportconst getEmbedding: EmbeddingFunction =async(text:string):Promise<Float32Array>=>{thrownewError("Embedding function not implemented — replace this stub with a real embedding provider");};Performance Considerations and Optimization
Indexing and Query Performance
The schema already includes indexes on session_id, timestamp, and confidence, covering the primary query patterns. sqlite-vec’s vector search is exact k-NN via linear scan by default, not approximate. This means query time scales linearly with the number of vectors stored. On a 2020-era laptop, queries against 10k vectors complete in single-digit milliseconds, but you should benchmark on your target hardware. Beyond that scale, query latency grows linearly with vector count, and alternatives like approximate nearest neighbor indexes or partitioning strategies become necessary.
The createDatabase() function enables WAL (Write-Ahead Logging) mode, which improves write throughput and allows concurrent reads from other processes while a write is in progress. This matters in agent architectures where a separate process (such as a monitoring tool or a second agent instance) reads the database while the main process writes, or where background compaction runs alongside active query serving.
Memory Budget Management
Two strategies prevent unbounded growth of the semantic store. First, LRU eviction by access_count: delete or archive semantic records with zero or low access counts older than a TTL threshold based on created_at (a reasonable starting point is 30 days with access_count = 0). Second, token-aware retrieval: the token_count column on episodic records and the content length of semantic records allow the agent loop to accumulate context up to a maximum token budget rather than blindly retrieving a fixed top-k.
Testing the Memory Store
Unit Testing with In-Memory SQLite
Passing :memory: as the database path to AgentMemoryStore creates a fully isolated, in-memory database that is discarded after each test. This makes tests fast and side-effect-free. The node:test runner with describe/it requires Node.js 18.13 or later.
import{ describe, it, beforeEach, afterEach }from"node:test";import assert from"node:assert/strict";import{ AgentMemoryStore }from"./agent-memory-store";describe("AgentMemoryStore",()=>{let store: AgentMemoryStore;beforeEach(()=>{store =newAgentMemoryStore(":memory:",3);});afterEach(()=>{store.close();});it("logEpisode returns a positive integer ID",()=>{const id = store.logEpisode("s1","user","hello");assert.ok(typeof id ==="number"&& id >0);});it("getRecentEpisodes returns only non-compacted rows for the session",()=>{store.logEpisode("s1","user","msg1");store.logEpisode("s2","user","other-session");const episodes = store.getRecentEpisodes("s1",10);assert.strictEqual(episodes.length,1);assert.strictEqual(episodes[0].content,"msg1");});it("returns nearest neighbor correctly by cosine distance",()=>{const embeddingA =newFloat32Array([1.0,0.0,0.0]);const embeddingB =newFloat32Array([0.0,1.0,0.0]);const query =newFloat32Array([0.9,0.1,0.0]);store.storeSemantic("Fact about TypeScript", embeddingA);store.storeSemantic("Fact about Python", embeddingB);const results = store.recallSemantic(query,2);assert.strictEqual(results.length,2);assert.strictEqual(results[0].content,"Fact about TypeScript");assert.ok(results[0].distance < results[1].distance);});it("recallSemantic increments access_count on retrieved records",()=>{const emb =newFloat32Array([1.0,0.0,0.0]);store.storeSemantic("tracked fact", emb);store.recallSemantic(newFloat32Array([1.0,0.0,0.0]),1);const results = store.recallSemantic(newFloat32Array([1.0,0.0,0.0]),1);assert.strictEqual(results[0].access_count,2);});it("recallSemantic on empty store returns empty array without throwing",()=>{const results = store.recallSemantic(newFloat32Array([1.0,0.0,0.0]),5);assert.deepStrictEqual(results,[]);});it("compactEpisodes with no argument uses compactionThreshold default",()=>{const store2 =newAgentMemoryStore(":memory:",3,0);store2.logEpisode("s1","user","old message");const compacted = store2.compactEpisodes();assert.ok(Array.isArray(compacted));store2.close();});it("getApplicableRules filters by minConfidence and parses JSON",()=>{store.storeRule("user is rude","respond calmly",0.9,[1,2]);store.storeRule("user is happy","match energy",0.3,[]);const rules = store.getApplicableRules(0.7);assert.strictEqual(rules.length,1);assert.deepStrictEqual(rules[0].source_episode_ids,[1,2]);});it("initializeSchema rejects non-integer embeddingDimension",()=>{assert.throws(()=>newAgentMemoryStore(":memory:",3.5),/Invalid embeddingDimension/);});});Using a 3-dimensional embedding space in tests keeps test data tri query path. The assertions verify correct ordering, relative distance, access count tracking, and input validation, catching regressions in the vector search pipeline
To run tests after compilation: node --test dist/agent-memory-store.test.js
Where to Go from Here
Extending the Architecture
A working memory tier, held in-process as a simple Map or array and never persisted, can model the agent’s scratchpad for the current task. This separates ephemeral reasoning state from durable memory without additional database writes.
For multi-agent scenarios, SQLite replication tools like Litestream (continuous streaming backup to S3-compatible storage) or LiteFS (distributed SQLitenot support macOS or Windows) enable cross-agent memory sharing without abandoning the SQLite foundation
What happens when the semantic store accumulates contradictions or redundant entries? Reflection loops address this: a background process periodically reviews the semantic store, identifies conflicts, consolidates entries, and adjusts procedural rule confidence scores. The three-tier architecture makes this possible because the agent can query, compare, and rewrite its own memory across all tiers.
The three-tier architecture makes this possible because the agent can query, compare, and rewrite its own memory across all tiers.
Production Hardening
Encrypt sensitive episodic data (user messages, personal information) at rest. The community sqlcipher fork provides transparent open- is an alternative but requires a paid commercial license from the SQLite Consortium. Note that WAL mode creates .db-wal and .db-shm files alongside the main database; ensure encryption covers all three files
Version schema migrations with a simple integer stored in SQLite’s user_version pragma, checked at startup, with migration functions applied sequentially. Monitoring should track table row counts, semantic store vector count, compaction frequency, and average query latency to detect runaway growth or degraded search performance before they impact agent behavior.
Sharing our passion for building incredible internet things.
