



Community Article
Community articles are authored by SitePoint Premium contributors. Content is screened before publication, and SitePoint reserves the right to moderate or remove articles that violate our guidelines. Views expressed are those of the authors and do not necessarily reflect those of SitePoint.
How Applicant Tracking Systems Read Resumes: 7 Checks Developers Should Make
Published inProgramming·
October 29, 2026
·Updated:October 29, 2026
The AI briefing for Developers
Stay up to date with AI tools, model releases, and developer workflows that matter.
Weekly. Free. One click to leave.
SitePoint Premium
Stay Relevant and Grow Your Career in Tech
- Premium Results
- Publish articles on SitePoint
- Daily curated jobs
- Learning Paths
- Discounts to dev tools
7 Day Free Trial. Cancel Anytime.
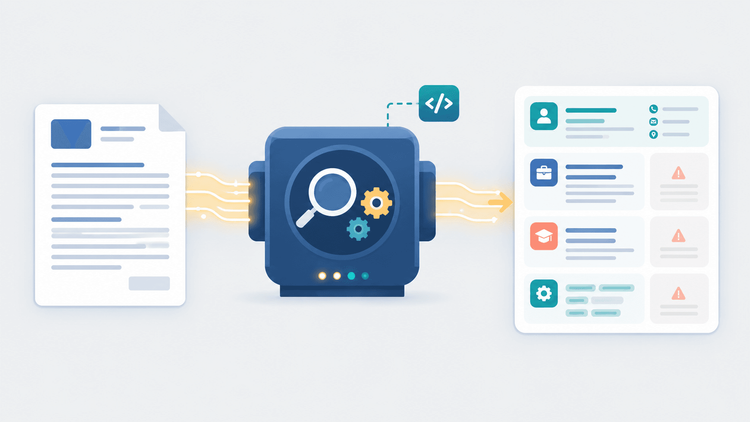
A resume that looks perfect on screen can look like a pile of scrambled text to a program. Applicant tracking systems (ATS) and hiring tools do not see your layout. They extract text from a file, guess where the sections are, and store what they find. If that step fails, the best experience in the world never reaches a human reader.
This matters whether you are sending your own resume or building a tool that processes thousands of them. This article walks through seven checks you can make with a few lines of Python, including one script you can run today.
1. Treat the Resume as Unstructured Data
A resume is a document with no guaranteed structure. One person writes “Work History”, another writes “Experience”, and a third uses a two-column layout that reads out of order. Any tool that processes resumes first has to turn this into predictable fields: contact details, sections, dates and skills.
Thinking in terms of a target schema helps. SitePoint’s article on JSON schema design for document AI shows how the structure of the labels you define determines whether a document pipeline works. The same idea applies here: decide which fields you need before you write any extraction code.
2. Extract the Text Before Judging the Result
Do not judge a resume by how it looks. Judge it by what comes out when you extract the text. SitePoint’s walkthrough on building a JSON dataset from PDF documents describes a pipeline that extracts text from PDFs and then cleans up common extraction artifacts. That cleanup step exists because raw extraction is rarely tidy. Read the raw output first, and note what is broken.
3. Know the Limits of Text Extraction
PDF files store where characters are placed on a page, not what they mean. The pypdf documentation on extracting text from a PDF says this directly: there is no semantic layer, spacing is hard to get right because text is absolutely positioned, and pypdf is not OCR software, so it will never extract text from images.
Two practical results follow. A resume saved as a scanned image has no extractable text at all. And fancy layouts such as columns, text boxes and tables can come out in the wrong order.
4. Check for the Basics Automatically
Once you can extract text, a short script can catch the common failures. This one reads a PDF and reports whether it contains text, whether an email address is found, and which standard sections are missing:
import refrom pypdf import PdfReaderSECTIONS =["experience","education","skills"]defcheck_resume(path):reader = PdfReader(path)text ="n".join(page.extract_text()or""for page in reader.pages)lower = text.lower()return{"has_text":len(text.strip())>50,"email_found":bool(re.search(r"[w.+-]+@[w-]+.w+", text)),"missing_sections":[s for s in SECTIONS if s notin lower],}Run it on a resume and look at the result. If has_text is false, the file is probably an image. If sections are missing, check whether your headings use unusual names. A passing result does not prove that every ATS will read the file the same way, but a failing result is a clear warning.
5. Compare Your Result With an Outside Checker
Different tools parse differently, so one script is only one opinion. A resume writing service such as ResumeCroc lists a free ATS resume checker among its tools, which is a quick way to see how another tool reads the same file. The linked page is a commercial service page, and every ATS behaves differently, so treat any checker as one data point and compare it with your own extraction results.
6. Keep the Formatting Simple
Most extraction problems come from layout. Single-column pages, standard headings, plain fonts and real text instead of images give parsers the best chance. Avoid putting contact details in headers or footers, since some tools skip them. If you are building a parser, test files with columns and tables on purpose so you know how your tool fails.
7. Keep a Small Set of Test Files
Create a folder of sample resumes: a clean one, a two-column one, a scanned one and one with unusual headings. Run your check against all of them whenever you change your parsing code. This turns “it seems to work” into something you can verify, and it makes regressions obvious.
Frequently Asked Questions
Do all applicant tracking systems read PDFs the same way? No. Parsers differ in how they handle layout, headers and tables, so test more than one file format and more than one tool.
Is a Word file safer than a PDF? Not necessarily. Both can parse well or badly depending on layout. Test your own file instead of assuming.
Can a script guarantee my resume will pass an ATS? No. A script can find obvious problems, such as missing text or headings, but each hiring tool has its own rules.
Summary
Hiring tools read text, not layout. Define the fields you care about, extract the raw text first, understand what PDF extraction cannot do, automate basic checks, compare with an outside checker, keep formatting simple, and test against a small set of sample files. The script above is short, but it moves the question from “does it look right” to “what does a program actually see”.
